
DeepSeek V4.1 Flash Launches at 70% Below V4 Pro: Pricing and Specs
Last updated: September 2026
DeepSeek released DeepSeek V4.1 Flash today, September 10, 2026, with off-peak output pricing of $0.60 per million tokens — 70% cheaper than V4 Pro's $1.98 for the same category. The new model ships with a 1M-token context window, a new 552B-parameter MoE architecture, native visual understanding, and 2,500-way concurrency. Open weights are already live on Hugging Face with a full technical report.
Source: DeepSeek official account on X
What exactly launched this morning?
V4.1 Flash is the smallest model in a brand-new architecture family from the Chinese lab, and it arrives with native visual understanding built in rather than bolted on. The API model string is deepseek-flash, and the pricing went live at 04:00 UTC.
The headline spec is a new Causal Encoder–Decoder architecture with 552B total parameters in a mixture-of-experts layout: 8B active parameters for input processing and 16B for output generation. Only a small slice of the network fires per token — that is the mechanical reason the price can drop this far without the model collapsing.
Memory efficiency improved too. KV cache now needs one quarter of the HBM and one third of the SSD storage of the previous generation, per the official announcement page.
Source: DeepSeek official docs
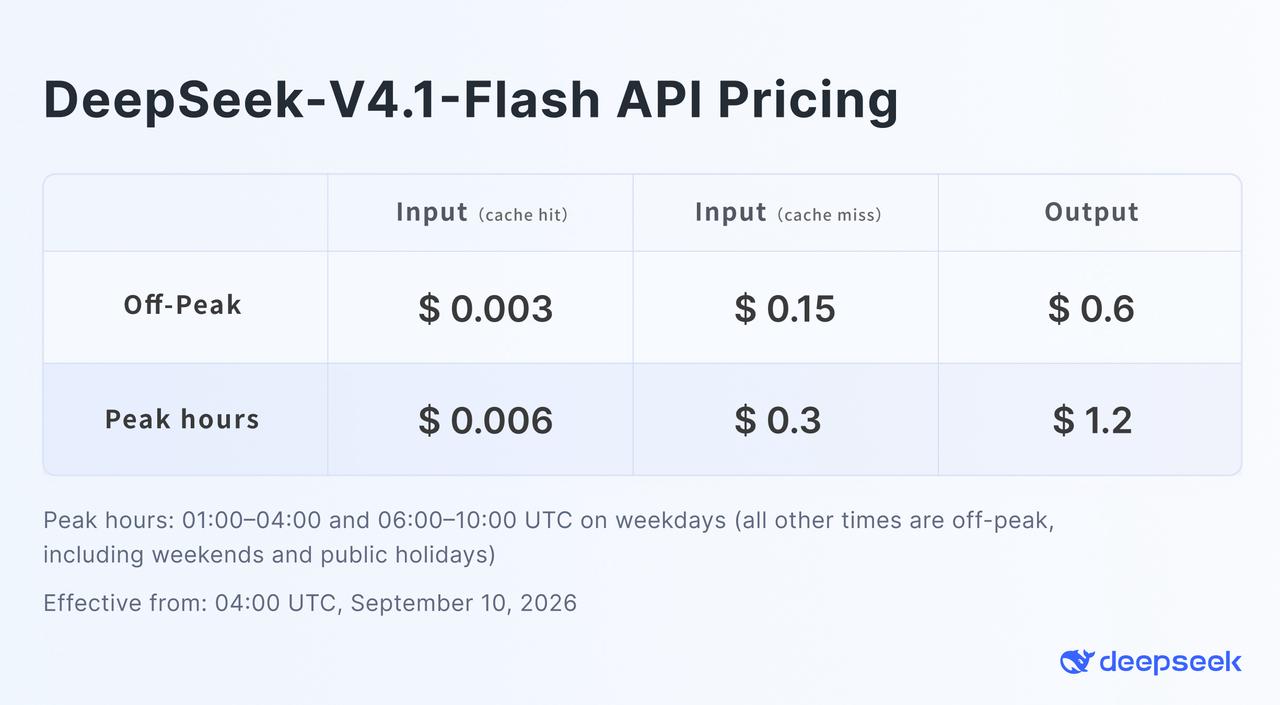
The full pricing table (per million tokens, USD)
| Category | Peak hours | Off-peak (50% discount) |
|---|---|---|
| Input, cache hit | $0.006 | $0.003 |
| Input, cache miss | $0.30 | $0.15 |
| Output | $1.20 | $0.60 |
For context, V4 Pro (the 0813 release) charged $3.96 peak / $1.98 off-peak for output and $1.32 / $0.66 for cache-miss input. That makes V4.1 Flash roughly 4.4× cheaper on cache-miss input and about 70% cheaper on output in both windows.
Peak hours — check them against your timezone
DeepSeek defines peak hours as 01:00–04:00 UTC and 06:00–10:00 UTC, Monday through Friday. Everything outside those windows gets the 50% off-peak discount automatically — no configuration, no coupon.
In practice: if your production traffic is heaviest during European mornings or US evenings, most of your calls land off-peak. Teams routing batch workloads through the off-peak windows can halve their bill by scheduling alone, before the per-token savings even enter the math.
Specs versus V4 Pro
| Spec | V4.1 Flash (today) | V4 Pro (0813) |
|---|---|---|
| Output price (off-peak) | $0.60 | $1.98 |
| Context window | 1M tokens | Shorter |
| Max output | 384K tokens | Shorter |
| Concurrency | 2,500 | 500 |
| Vision | Native | Separate model |
The concurrency jump from 500 to 2,500 simultaneous requests matters as much as the price for agent-heavy applications. Press coverage from forkast estimates agent operating costs falling by as much as 80%, and 36Kr measured an 88% reduction in cache disk usage on long-form workloads.
What the benchmarks say so far
Early independent and press coverage published within hours of launch:
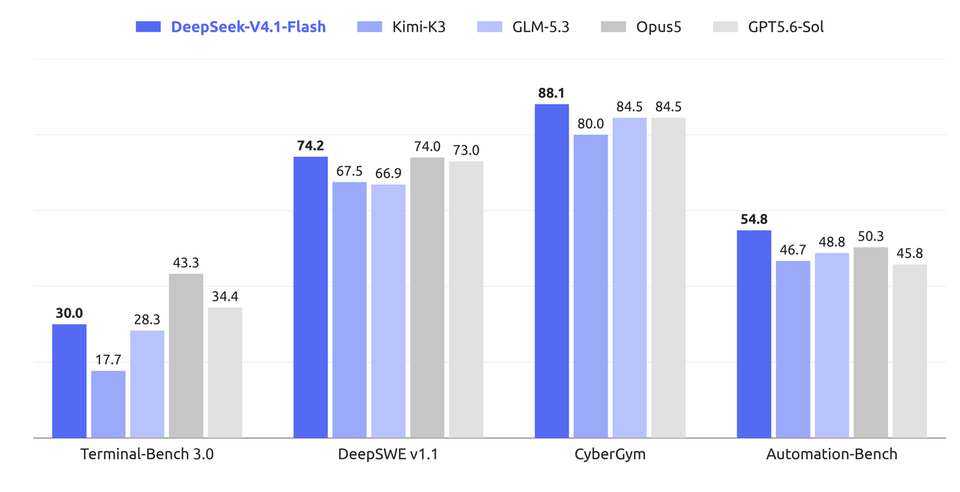
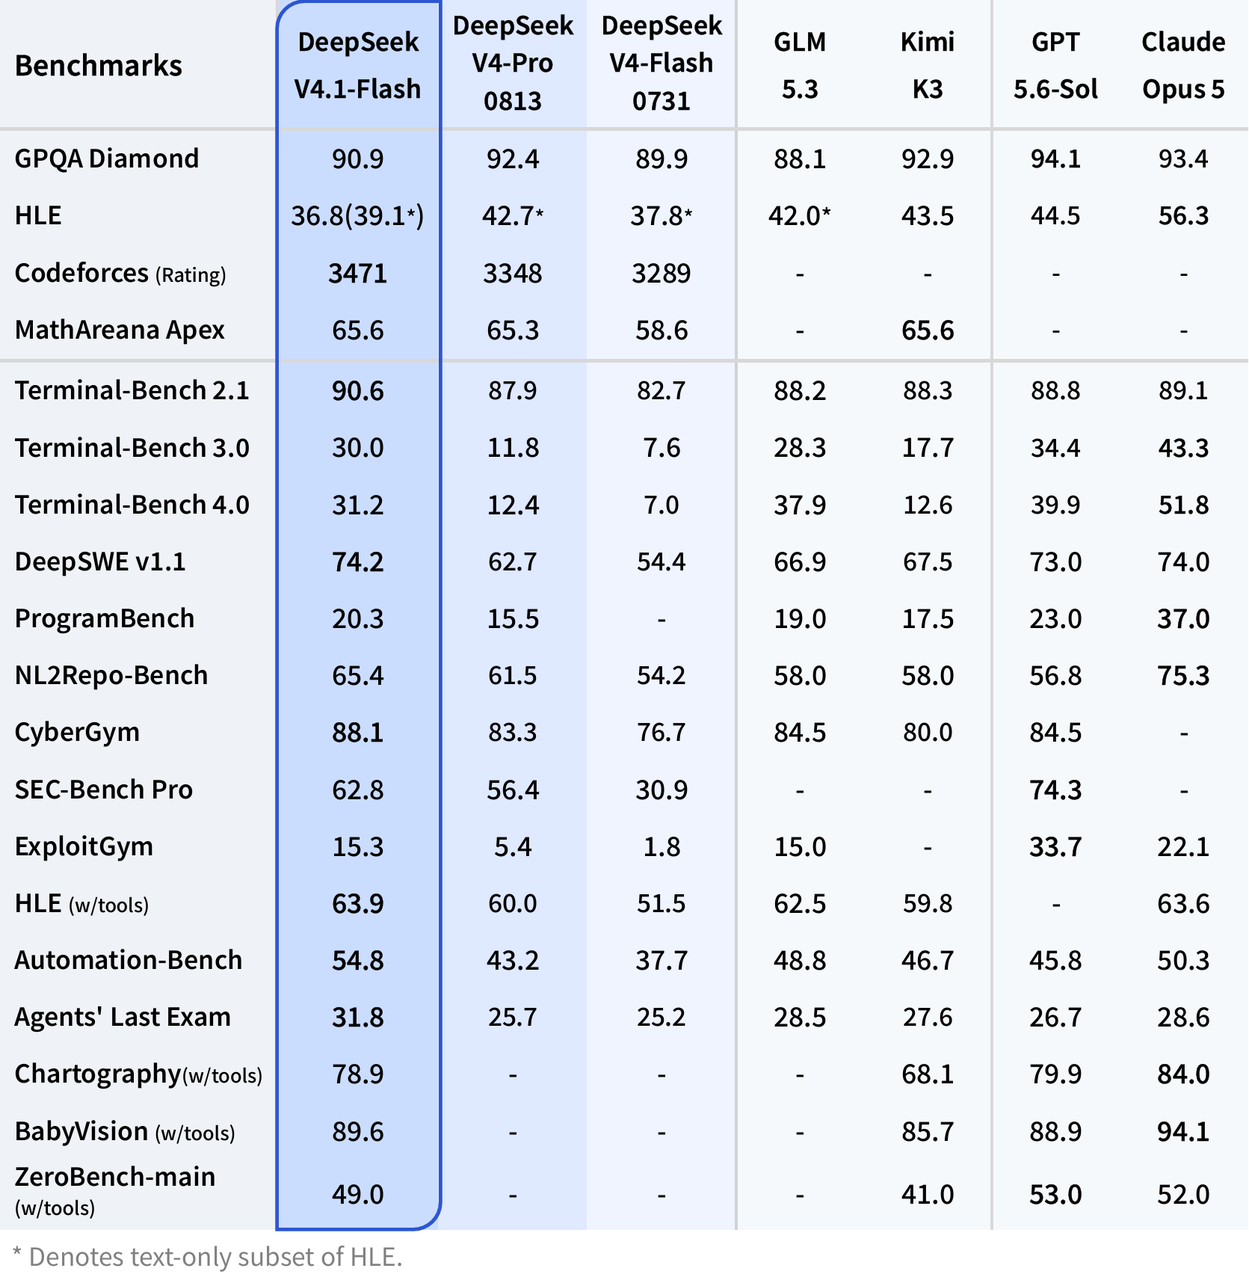
- SCMP reports it beats Kimi K3 on cybersecurity and coding benchmarks.
- OfficeChai finds it matches GPT 5.6 Sol and Claude Opus 5 on some benchmarks at substantially lower pricing.
- Geeky Gadgets measured 427 tokens/sec in yesterday's beta build, with other outlets confirming 400+ token throughput.
- MarkTechPost highlights the FP4 KV cache and cross-layer attention reuse as the efficiency tricks doing the heavy lifting.
Source: DeepSeek official docs
Treat these as first-day signals rather than settled conclusions — full independent evaluations will take weeks. But the pattern matches DeepSeek's history: launch cheap, open the weights, let the community verify.
One pricing line deserves more attention than it is getting: the cache-hit rate of $0.003 per million tokens off-peak is the lowest the company has ever published in any category. Workloads that re-read the same long system prompt or document set on every call — agent loops, retrieval pipelines, coding assistants with large context — will see most of their input tokens land as cache hits, which pushes effective input costs below a cent per two million tokens read. For teams that fled to local caching layers to protect their margins, this weakens the main reason that layer existed.
Why this matters for anyone building with LLMs
Three practical consequences, regardless of where you deploy:
- Agent economics just shifted again. An agent that reads long documents and writes long responses is exactly the workload where output tokens dominate cost. A 70% output-price cut changes which use cases clear the profitability bar.
- Check your routing before September 14. DeepSeek is rerouting V4 Pro traffic to V4.1 Flash starting 12:00 Beijing time on September 14 (04:00 UTC) at Flash prices, until a future V4.1-Pro arrives. The older
deepseek-v4-flashanddeepseek-v4-flash-vision-expmodels are retired, with their requests redirected to V4.1 Flash for now. - Self-hosting has a real ceiling. The weights are open on Hugging Face (deepseek-ai/DeepSeek-V4.1-Flash, with the PDF technical report), but large-scale self-hosting requires what the company calls a "2000 GPU + storage cluster" setup. Standard deployments via WorkBuddy/CodeBuddy and OpenCode are the practical path, and version 0.1.5 of the open-source Harness framework already supports the new model.
We covered the previous generation in our DeepSeek V4 and V4 Pro review and tracked the V4 Flash Vision experiment — if you built on either, this release directly affects your stack. Our Harness agent framework walkthrough covers the deployment tooling in depth.
Honest limitations to weigh
The transition is not painless. Press reports (unconfirmed by the company) document developer pushback over the abrupt model swap with limited transition time. Separate media reports claim DeepSeek is preparing a Shanghai IPO — treat that as press speculation until an official filing exists. And if your application depends on V4 Pro's exact behavior, the September 14 forced reroute is a real migration deadline, not a suggestion.
Frequently asked questions
What is DeepSeek V4.1 Flash?
A new model released September 10, 2026, built on a new Causal Encoder–Decoder architecture with 552B MoE parameters (8B active for input, 16B for output), native visual understanding, a 1M-token context, 384K max output, and 2,500-way concurrency. The API model string is deepseek-flash.
How much does DeepSeek V4.1 Flash cost per million tokens?
Cache-hit input costs $0.006 peak / $0.003 off-peak; cache-miss input $0.30 / $0.15; output $1.20 / $0.60. Off-peak pricing is an automatic 50% discount outside peak windows, with no configuration required.
Is V4.1 Flash better than V4 Pro?
On cost, context, and concurrency, clearly yes: 70% cheaper output, 1M vs shorter context, and 2,500 vs 500 concurrent requests. On quality, first-day press benchmarks put it near GPT 5.6 Sol and Claude Opus 5, but independent verification is still early.
What are DeepSeek API peak hours in UTC?
Monday to Friday, 01:00–04:00 UTC and 06:00–10:00 UTC. All requests outside those windows are billed at the 50%-discounted off-peak rate automatically.
Is DeepSeek V4.1 Flash open-weight?
Yes. The weights are published on Hugging Face as deepseek-ai/DeepSeek-V4.1-Flash alongside a PDF technical report. Large-scale self-hosting requires roughly 2,000 GPUs plus a storage cluster per the company's guidance.
Will deepseek-v4-pro stop working?
Not immediately. From September 14, 2026, 12:00 Beijing time, V4 Pro requests are rerouted to V4.1 Flash and billed at Flash prices, until the upcoming V4.1-Pro launch. The older v4-flash and v4-flash-vision-exp models are already retired with temporary redirects.
Your next step
Grab an API key from the DeepSeek docs, run your existing eval suite against deepseek-flash during off-peak hours, and compare both quality and invoice against your current model over 48 hours. For the wider competitive picture, see our coverage of the GPT-6 Astra launch and Claude Fable 5.1.
Sources
- Official DeepSeek V4.1 Flash announcement — full launch details, pricing, and architecture
- Model weights on Hugging Face — open weights and the technical report PDF
- DeepSeek official account on X — the launch announcement post
- DeepSeek API pricing page — the updated official price table
Start Your Journey with Truescho
Whether you're searching for a scholarship or planning to study abroad, truescho.com gives you everything.
Get Started Free →